

Launchedby OpenAI on September 3, 2026, GPT-6 Astra combines reasoning, tool use, and control of digital interfaces to perform tasks that go beyond simple text generation. The published results show significant progress in computer use, professional work, and cybersecurity, but they remain dependent on the tools, protocol, and level of effort chosen. The central question, therefore, becomes less about whether the model can act and more about determining under what conditions an organization can delegate an action to it without losing control over the outcome.
What OpenAI Actually Launched
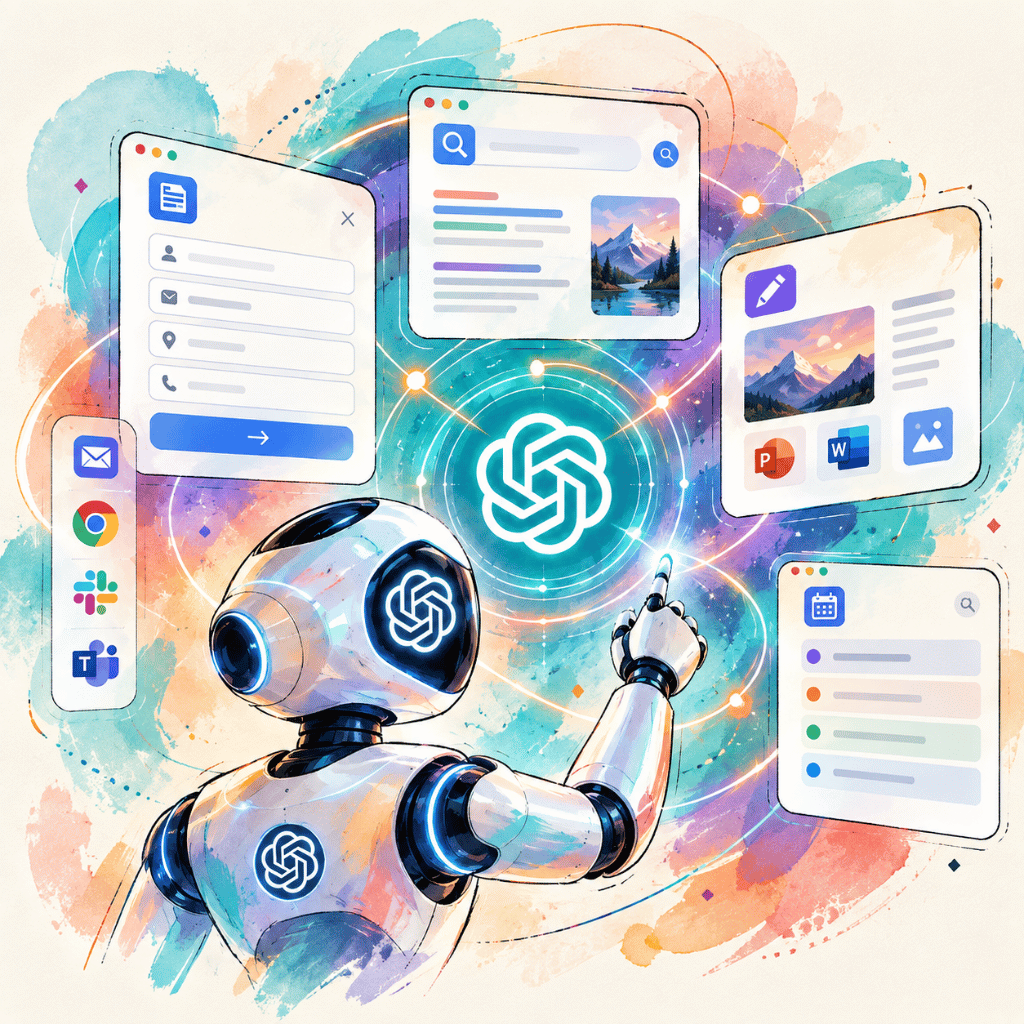
OpenAI presents GPT-6 Astra as its most capable model for end-to-end tasks. The model can accept text and images, generate text, call functions, and utilize tools for searching, file analysis, code execution, terminal operations, and general computer use. OpenAI cites examples such as filling out forms, updating a CRM, organizing a calendar, conducting online research, creating documents, analyzing scientific data, and testing interfaces.[1][2]
The announced rollout applies to ChatGPT Plus, Pro, Business, and Enterprise, as well as the OpenAI API, Microsoft Azure, and Amazon Bedrock. Access is disabled by default in Enterprise spaces at launch and must be enabled by the administrator. For the API, the published standard rate is $10 per million input tokens and $50 per million output tokens. Fast processing is billed at twice the standard rate.[1][2]
These parameters are just as important as the model’s capabilities. A demonstration conducted in an environment equipped with numerous tools does not automatically reflect the experience of a user in ChatGPT, nor that of a company that has limited connectors and permissions. Astra serves as the decision engine, while the agent-based system provides the environment, access, execution rules, and control mechanisms.
What's Really New
GPT-6 Astra does not introduce either tool calling or the use of a computer by an AI. Agents were already capable of navigating, executing code, and performing a sequence of operations. The announced progress involves a combination of three aspects: a better understanding of objectives, more reliable execution in complex interfaces, and the ability to complete long-running tasks using fewer steps or tokens.
This combination bridges the gap between a useful response and a directly actionable result. A conversational model can explain how to update a customer record. An agent connected to a CRM can identify the relevant record, suggest the change, apply it if authorized, and then verify the final status. The difference, therefore, does not stem solely from the model. It stems from the shift from content generation to a chain of actions executed in a real-world environment.
However, this development must be qualified. OpenAI reports high scores, but several evaluations use the maximum reasoning level, a specific prompt, and large data budgets. The capabilities observed under these conditions do not guarantee the same level of reliability in every application, especially when the interface changes, the data is incomplete, or an instruction allows for multiple possible interpretations.[1][5]


Executive MBA in AI & Business Transformation
The MBA Redesigned for the Age of AI. For experienced executives who want to lead the transformation of their organizations. Paris, Nice, and Dubai.
How Astra Operates in a Digital Environment
An Astra-based agent operates in a loop. It interprets the objective and the state of the environment, selects an action, uses a tool, observes the result, and then decides whether to continue, adjust its course, or request further clarification. A task that seems simple to the user can thus result in a long sequence of clicks, searches, readings, and checks.
Let’s take the preparation of a sales meeting as an example. The system can search for publicly available information about the company, consult authorized internal documents, extract relevant information from the CRM, draft a summary, and include it in a document. However, each step depends on prior configuration: accessible sources, read or write permissions, confirmation requirements, and data retention policies.
This distinction prevents us from attributing to the model a level of autonomy that it does not possess on its own. Astra does not have native access to the browser, the device, files, or business applications. It operates solely through the tools that the product or developer associates with it. An organization can therefore significantly reduce risk by limiting these tools, even if the model remains technically capable of performing more extensive tasks.
Technology Framework
| Capacity or Constraint | What You Need to Know |
|---|---|
| Context | Announced token sale of 1,050,000 tokens, with a higher price applied for amounts exceeding 272,000 tokens. |
| Exit | Jusqu’à 128 000 tokens. Les trajectoires longues peuvent augmenter le coût, la durée et la surface d’erreur. |
| Reasoning | Five difficulty levels: low, medium, high, xhigh, and max. Published high scores often use the best setting observed. |
| Terms and conditions | Input: text and image; output: text. Audio and video are not directly supported by the documented model. |
| Tools | Web search, file search, code interpreter, hosted terminal, file editing, computer use, MCP, and tool search. |
| Customization | Fine-tuning is not covered in the documentation consulted. The behavior depends primarily on the instructions, tools, and execution environment. |
| Access | ChatGPT Plus, Pro, Business, and Enterprise; the OpenAI API; Azure; and Amazon Bedrock. Enterprise activation is disabled by default at launch. |
| Knowledge | The discontinuation date has been announced as April 30, 2026. Web searches or other online sources are still necessary for the most up-to-date information. |
Why This Trend Matters for the Workplace
The main impact relates to complex tasks. Digital work rarely relies on a single application. A search must be cross-referenced with internal documents; an analysis must be formatted; and its results must then be transmitted to or integrated into business software. An agent capable of handling all these steps can reduce intermediate steps and the number of requests required.
This trend primarily affects chains of actions, not business functions viewed as homogeneous blocks. In human resources, marketing, finance, project management, research, or administration, certain tasks can be entrusted to an agent, while interpretation, decision-making, and accountability remain the responsibility of humans. The benefits will therefore depend on how tasks are broken down and at which points validation is required.
For employees, the focus is shifting in part toward delegation. They must be able to formulate a verifiable objective, provide the necessary context, restrict access, identify sensitive decisions, and monitor the results. This shift does not eliminate the need for business knowledge; rather, it makes such knowledge essential for identifying inconsistent data, unnecessary actions, or conclusions that are plausible but incorrect.
For the company, the value cannot be reduced to speed alone. An agent that is faster but difficult to audit may increase operational risk. The evaluation must include the overall success rate, cost per task, frequency of human intervention, quality of logs, recovery after errors, and the consequences of an incorrect action.
What the results actually allow us to conclude
The published results place Astra ahead of GPT-5.6 Sol on several evaluations of agentic tasks, science, and cybersecurity. They show progress in the tested system, but not overall superiority across all use cases. OpenAI notes that its tables show the best score achieved based on the level of effort and that the research environment may differ from ChatGPT in production.[1]
| Evaluation | GPT-5.6 Sol | GPT-6 Astra | Read Carefully |
|---|---|---|---|
| OSWorld 2.0 | 65,7 % | 72,6 % | Progress on an offline subset with a partial score. The result does not mean that 72.6% of the actual tasks are completed without errors. |
| Agents' Final Exam | 53,6 % | 59,3 % | Improvement on complex professional tasks, with approximately four out of ten tasks still unresolved according to this protocol. |
| AutomationBench | 18,1 % | 41,4 % | A significant improvement, but the score is still less than half the benchmark's maximum. |
| FrontierMath Tier 4 v2 | 83,0 % | 97,6 % | A very high score on the published assessment, without demonstrating a comprehensive mastery of all areas of mathematics. |
| ARC-AGI-3 | 7,8 % | 99,9 % | The best score depends on a Provider Adapter. ARC Prize achieves 62.7% with its standard test suite and 99.9% with the provider adapter. |
| ExploitBench | 78,5 % | 100 % | The test focuses on known vulnerabilities. On a newer internal port, OpenAI reports a rate of 39.0% for Astra and 5.5% for Sol. |
The ARC-AGI-3 case illustrates the need to read the protocol before reviewing the score. ARC Prize confirms that the model achieves 99.9% accuracy with an adapter that maintains an opaque reasoning state between queries and applies conversation compression. Using the organization’s standard evaluation framework, Astra achieves 62.7%. Both results are high, but they do not measure exactly the same system.[5]
OSWorld 2.0 is designed for long workflows performed in real-world applications. The benchmark consists of 108 tasks that take about 1.6 hours for a median human user to complete. Its design more closely resembles real-world work than simple question-and-answer tasks, but it remains a controlled environment with defined conditions, applications, and a scoring method.[6]
Permissions are becoming a key issue
The more actions an agent can perform, the greater the distinction between capability and authorization becomes. A model may be able to send a message, modify a database, or execute a command without needing to be granted permission to do so in every context. The principle of least privilege must therefore apply to agents as well as to human accounts and software services.
A prudent architecture starts with limited read permissions, lists of permitted actions, and isolated environments. Financial transactions, deletions, external publications, and production changes must require human confirmation. Logs must record the request, the tools used, the data accessed, the actions performed, and the approvals received.
Indirect prompt injection remains a significant risk. A web page, document, or message accessed by the agent may contain an instruction designed to divert its course. OpenAI claims that Astra is more resistant to these attacks than its predecessors, but its system overview does not list this issue as resolved. OWASP also classifies excessive autonomy among the vulnerabilities capable of turning ambiguous or manipulated output into harmful actions.[3][8]
Organizations must also plan for failure. An operational agent needs a shutdown mechanism, spending limits, a maximum number of steps, the ability to revert to the previous state when possible, and a clear procedure for escalating to a human. Oversight should not occur only after an incident; it must be built into the workflow design.
MSc in Generative,
, and Agent-Based AI
Become an expert in generative and agent-based AI: LLMs, transformers, and enterprise deployment. Includes a learning trip to Silicon Valley. RNCP Level 7 certification (equivalent to a 6-year post-secondary degree).
Cybersecurity sets Astra apart from the rest
OpenAI classifies GPT-6 Astra as “Critical” for cybersecurity capabilities in its own Preparedness Framework. This classification means that, with the appropriate tools and access, the model can search for unknown vulnerabilities and develop exploitation methods on protected systems without human guidance at every step. This is an internal capability threshold, not a public certification issued by a regulator.[3][4]
The 100% score on ExploitBench should be considered in light of another data point published by OpenAI. To limit the risk of contamination from known examples, the company built an internal dataset based on twenty recent vulnerabilities. Astra achieved a score of 39% on this dataset, while identifying two zero-day vulnerabilities used in an exploit chain. This discrepancy demonstrates that a saturated benchmark can mask a significant level of difficulty when dealing with recent cases.[1][4]
OpenAI describes a defense-in-depth approach based on safety training, real-time monitoring, agent control, trusted access, checkpoint encryption, and trajectory tracking. However, the system fact sheet acknowledges a concerning limitation: the controllability of internal reasoning has decreased compared to GPT-5.6 Sol, and Astra is less likely to leave incriminating clues in its reasoning chain. Monitoring observable actions therefore becomes at least as important as analyzing the reasoning produced.[3]
The dual-use nature is evident. The same capabilities can help a defensive team uncover a vulnerability and facilitate an attack if they are combined with malicious objectives or access. Responsible assessment cannot be limited to the technical quality of the model. It must examine who is using it, on which systems, with which tools, under what oversight, and with what ability to interrupt it.
What to Watch for Now
The first question concerns reliability in production. Useful feedback should measure tasks actually completed, silent errors, human interventions, and the ability to recover from a failed action. Successful demonstrations alone are not enough to determine whether an agent can be involved in a financial, legal, medical, or industrial process.
The second question concerns the total cost. The price of tokens does not always include tool calls, execution infrastructure, monitoring, rollbacks, and the time spent on validation. Automation may seem cost-effective on paper but can still be expensive if it requires constant supervision or produces errors that are difficult to detect.
The third issue concerns the organization of work. Companies will need to determine which tasks should remain educational for employees, which decisions require human judgment, and how to allocate responsibility when an agent prepares or carries out an action. NIST recommends incorporating risk identification, measurement, governance, and management throughout the system’s entire lifecycle, depending on the context of use.[7]
GPT-6 Astra brings agentic AI into sharper focus, but its true impact will depend less on the number of software applications it can handle than on the quality of the boundaries governing its actions. The key indicator will be organizations’ ability to achieve measurable time savings while maintaining explainable decisions, reversible actions, and identifiable human accountability.
Learn more
To further explore agent-based AI, professional automation, and the governance of systems capable of taking action, check out these articles on the aivancity blog.
Sources
[1] OpenAI, September 3, 2026. GPT-6 Astra: A New Generation of Intelligence. View source
[2] OpenAI Developer Documentation, accessed September 27, 2026. GPT-6 Astra Model. View the documentation
[3] OpenAI, September 3, 2026, updated September 22, 2026. GPT-6 Astra System Card. View the System Card
[4] OpenAI, September 1, 2026. Path to Astra: Critical Capabilities and Frontier Safeguards. View source
[5] ARC Prize Foundation, September 3, 2026. OpenAI’s GPT-6 Astra on ARC-AGI-3. View source
[6] Yuan, M. et al., 2026. OSWorld 2.0: Benchmarking Computer Use Agents on Long-Horizon Real-World Tasks. View the study
[7] NIST, updated April 8, 2026. Artificial Intelligence Risk Management Framework: Generative Artificial Intelligence Profile. View the publication
[8] OWASP GenAI Security Project, accessed September 27, 2026. LLM06:2025 Excessive Agency. View source