

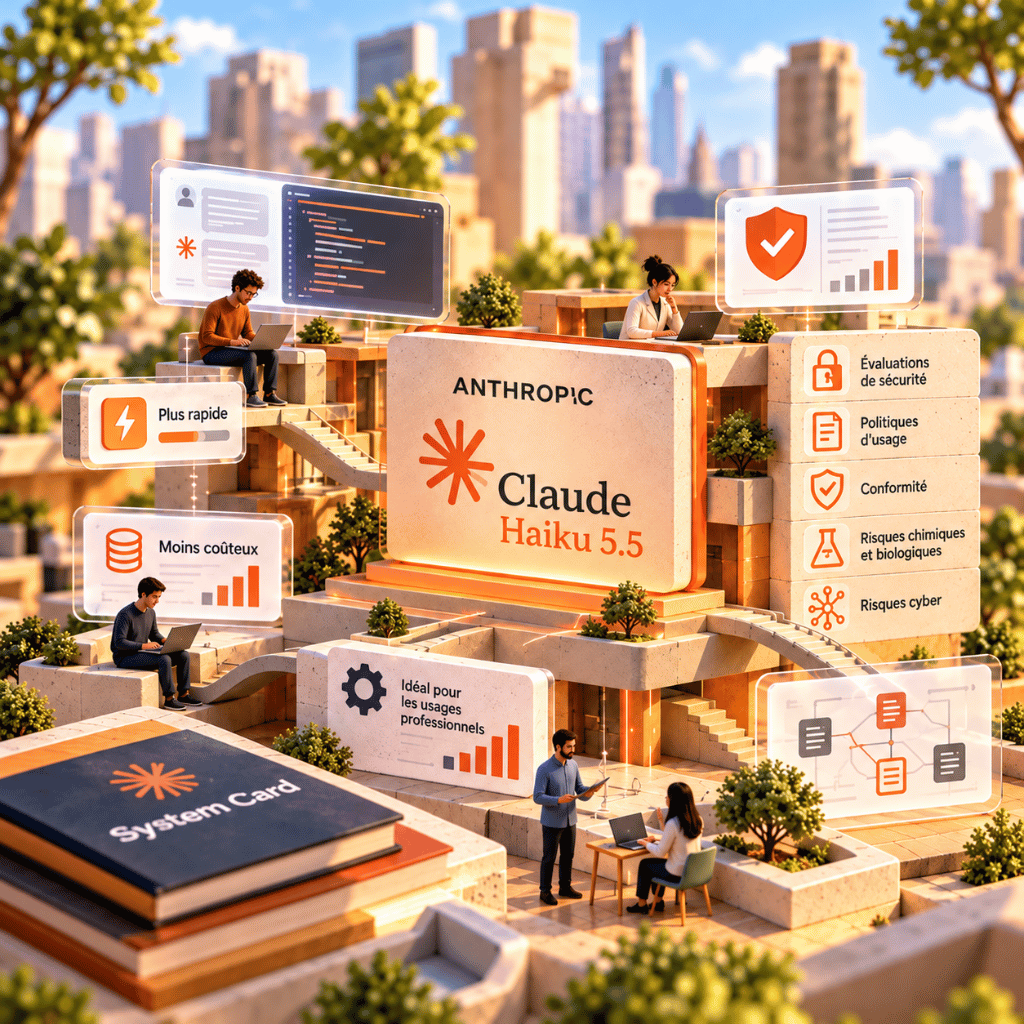
Published on October 7, 2026, Claude Haiku 5.5 strengthens the Anthropic’s compact lineup with reduced costs, a broader context and some reported progress in tool use, reasoning, and safety. This development does not turn Haiku into universal model : Its strategic importance lies primarily in the large-scale execution of clearly defined tasks. It remains to be seen where the balance between capacity, speed, cost, and risk actually becomes advantageous.
What Anthropic Actually Published
Anthropic has launched Claude Haiku 5.5 and published its system card, which outlines the key assessments of capabilities, safety, and alignment conducted prior to deployment. The model is available on the Claude platform, Amazon Web Services, Google Cloud, and Microsoft Azure. It is designed for high-volume and latency-sensitive use cases, including classification, extraction, synthesis, and certain sub-agent tasks.[1]
The documentation specifies a context window of one million tokens, a maximum output of 128,000 tokens, and several effort levels. This configuration allows you to balance computation, expected quality, latency, and cost, without guaranteeing the correct resolution of a complex query.[3]
The term “small model” should also be interpreted with caution. Anthropic does not disclose the number of parameters or the detailed architecture of Haiku 5.5. Here, it refers to a product class that is faster and less expensive than Sonnet or Opus, not necessarily a lightweight model in the sense of on-premises deployment or a small hardware footprint.
What’s Really New
The first new feature is related to pricing. For up to 100,000 tokens, Anthropic charges $0.10 per million tokens for input and $0.50 for output. Beyond that, the rates increase to $0.50 and $2.50. The company estimates that the average execution cost is about 75% lower than that of Haiku 4.5.[1] This average varies depending on length, cache, and effort level.
The second new feature concerns the use of tools. Haiku 5.5 is designed for short, repetitive tasks, but also as a subagent controlled by a more powerful model. Sonnet or Opus can develop a plan, while multiple instances of Haiku perform targeted searches, extractions, or verifications. The unit cost then becomes a strategic consideration.
Finally, Haiku 5.5 introduces a new tokenizer. According to the documentation, the same text yields approximately 30% more tokens compared to Haiku 4.5.[3] The reduction in the listed rate should therefore not be automatically applied to every invoice. Companies must recount their corpora, test their prompts, and measure the full cost of the workflow.
How to Integrate Haiku 5.5 into an Enterprise Architecture
This model can be useful when a task is frequent, clearly defined, and easily controllable: sorting requests, routing tickets, extracting fields, summarizing documents, preparing a response, or searching for information within a content portfolio. In these situations, the few seconds saved and the few cents saved quickly add up when scaled to millions of calls.
The choice should not be based on an overall ranking. A robust architecture can distribute tasks based on their difficulty, sensitivity, and cost of error. Haiku handles routine operations; a more powerful model intervenes in ambiguous cases; and a human then validates high-impact decisions. This approach requires documented thresholds, logging, and an escalation mechanism.
Why Small Models Are Becoming Strategic
In a prototype, the cost of a response seems secondary. In production, it determines which tasks can be automated on a long-term basis. A compact model can make functions that were previously too costly viable: continuous quality control, processing large volumes of documents, background assistance, or the orchestration of multiple subagents.
Speed also affects the user experience. A voice assistant, customer service, or navigation tool loses its appeal if every step involves a wait. A fast model can serve as the operational layer of a complex system, provided its limitations are understood.
This aspect explains the strategic nature of the launch. Anthropic is expanding its product lineup, with each model playing a different role. Competition is thus shifting from peak performance to the cost of a successful task, latency, and the governance of a set of models.


Executive MBA AI & Business
Transformation
The MBA reimagined for the age of AI. For experienced executives who want to lead their organization’s transformation. Paris, Nice & Dubai.
What the results actually allow us to conclude
The published results show significant improvement over Haiku 4.5 across several evaluations. However, they do not demonstrate overall superiority or guaranteed reliability in production. The scores are from Anthropic, using protocols, effort budgets, and environments that may differ from those of an enterprise.[1][2]
| Review | Haiku 4.5 | Haiku 5.5 | A Cautious Read |
|---|---|---|---|
| GDPval-AA v2.1 | 735 | 1,620 | Improvements in professional tasks, with a consistent lead over Sonnet 5.5. |
| OSWorld 2.1 | 15.7% | 72.4% | Significant increase in the offline subset of computer usage. |
| Humanity’s Last Exam | 10.2% | 45.9% | Results obtained without tools; sensitive to force settings and protocol. |
| Terminal-Bench 4.0 | 0.0% | 39.2% | Progress in agent-based coding, but Sonnet 5.5 achieves 70.6% in the published table. |
| Chartography | 6.4% | 46.4% | Improvement in visual reasoning without establishing overall robustness. |
Customer feedback provides additional insights but does not replace independent evaluations. HubSpot reports a score of 92.8% for its CRM suite, while AlphaSense reports an improvement from 0.76 to 0.84 across 400 document queries.[1] These results are specific to their respective environments.
The most solid conclusion is therefore relative: Haiku 5.5 represents a substantial improvement within the Haiku class. It remains incremental at the cutting edge, as Sonnet and Opus retain an advantage on long, complex, or highly agent-based tasks. The potential breakthrough lies less in any single capability than in the efficiency of a system that can deploy the model on a very large scale.
Security, Legal, and Liability Issues
The system card specifically covers dangerous queries, child safety, mental health, bias, malicious agentic uses, prompt injection, and alignment. Anthropic states that Haiku 5.5 is its most robust Haiku model against prompt injection and that, on certain adaptive tests, it performs similarly to its state-of-the-art models.[2] These pre-deployment evaluations reduce uncertainty without eliminating novel attacks or configuration errors.
The security controls are said to be more restrictive than those in Haiku 4.5, while allowing more leeway for defensive uses than those in Sonnet 5.5. Offensive penetration tests must be blocked, while certain professionals may request verified access. In biology, filters allow legitimate research but restrict queries deemed dangerous.[1]
In the European Union, a system card contributes to risk documentation and analysis but does not serve as a certificate of compliance. The AI Regulation establishes documentation, transparency, and copyright compliance obligations for providers of general-purpose models, with stricter requirements for models posing systemic risk.[4] Deployers must also analyze the use case, the data, and the individuals affected. NIST recommends risk management throughout the entire lifecycle.[5]
What to Watch for Now
The first issue will be that of reproducibility. Independent tests will need to compare Haiku 5.5 to other compact models using the same environment, the same tools, the same budget, and actual observed cost metrics. It will also be necessary to monitor performance stability when prompts exceed 100,000 tokens and move to a different pricing tier.
The second question concerns deployment in a business environment. Will the model remain reliable when it accesses unreliable content, calls upon multiple tools, or acts as a subagent over long sequences? Useful metrics will include not only average accuracy but also the escalation rate, false positives, unauthorized actions, auditability, and the cost of a successfully validated task.
Claude Haiku 5.5 thus represents a strategic advance in how computing is distributed and applications are industrialized, but only an incremental improvement in the overall hierarchy of capabilities. Its actual impact will depend on organizations’ ability to select the right tasks, measure errors, and maintain appropriate oversight. Will the next competitive advantage come from the most powerful model, or from the architecture that knows how to deploy each model in the right place?
To learn more
To continue this discussion on Claude models, safeguards and the governance of agent-based systems , check out these analyses from the aivancity blog as well.
Sources
[1] Anthropic. (October 7, 2026). Claude Haiku 5.5. View source
[2] Anthropic. (October 7, 2026). Claude Haiku 5.5 System Card. View the technical specifications
[3] Anthropic, Claude Platform Documentation. (2026). Claude Haiku 5.5 Overview and What’s New. View the documentation
[4] European Commission. (2026). General-purpose AI obligations under the AI Act. View source
[5] National Institute of Standards and Technology. (2024, updated 2026). Artificial Intelligence Risk Management Framework: Generative Artificial Intelligence Profile. View the framework at